MetaFacility expansion

Tens of thousands of Nvidia GPUs sit idle in Meta's Prometheus supercluster, just waiting for a failure
What happened

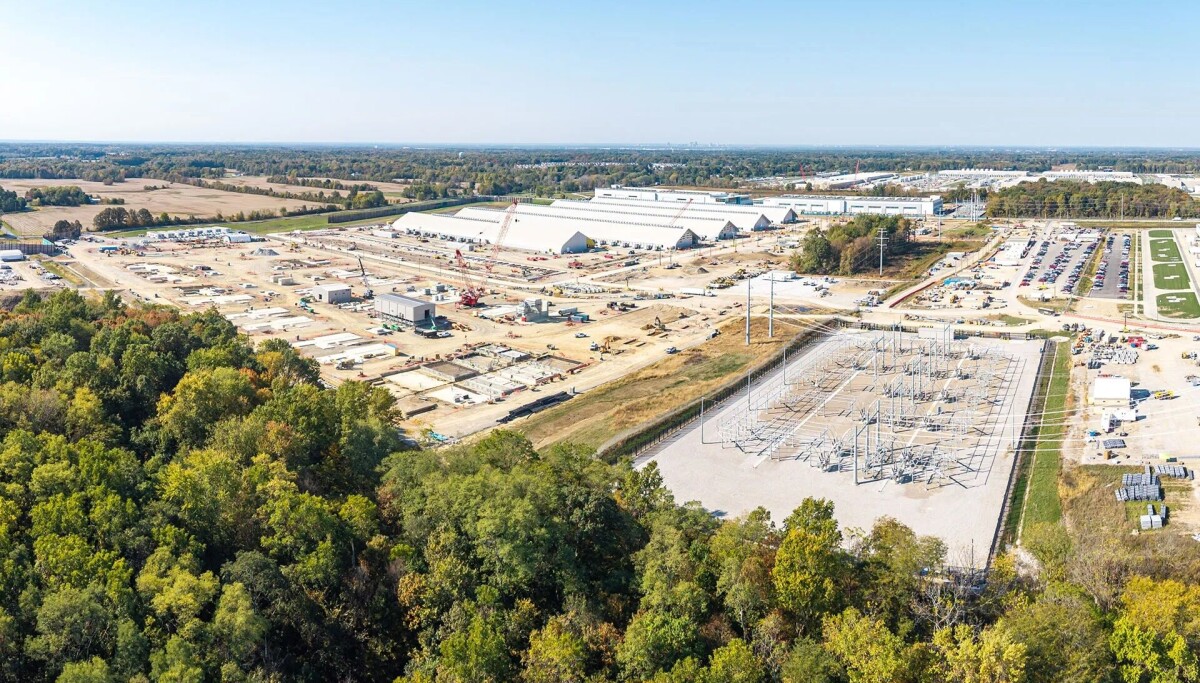
Meta is building and scaling its Prometheus supercluster compute deployment in New Albany, Ohio, to eventually reach a gigawatt of capacity spanning approximately one million accelerators.

Source

Article excerpt

Highlighted: the sentence this signal was extracted from

systems And other fun facts about how Zuckercorp aims to keep a million GPUs running long enough to train a model More than 11 percent of the GPUs at Meta's Prometheus supercluster in New Albany, Ohio, are either dead or sitting idle waiting to step in when the next drops out, Zuckercorp revealed this week. The massive pool of redundant GPUs is just one of several measures the hyperscaler has taken to keep its AI training runs on track. Prometheus is among Meta's largest compute deployments to date. Powered by Nvidia's Grace Blackwell and (soon) Vera Rubin rack systems, Meta says the supercluster will eventually scale to a gigawatt of capacity spanning about a million accelerators. But as anyone who has worked on a large scale compute cluster understands, whether for LLM training or traditional HPC workloads, more chips inevitably means more problems. In an eight-GPU node, the chance of having a GPU fail is relatively low. In a 100,000-GPU cluster, failures are unavoidable. Meta is building something that's 10x larger and requires distributed training runs across multiple datacenters. Keeping the entire thing humming long enough to reach the next checkpoint becomes a major headache. In a blog post published this week, Meta offered a unique look at the work it's done to keep failures from derailing the development of models like Muse Spark or its most recent release Muse...

Keep reading with a free account

The rest of this article, and every signal for Meta, is in your free account.

Extracted by Autobound

From the Signal API record
Event
Facility expansion

What this signalsA bigger facility often needs new equipment, systems and services.

Location
New Albany, Ohio, United States

More facility expansion signals at other companies

The full record

From the Signal API record

Extraction

Confidence
92%
Detected
Oct 20, 2026
signal_type
news
signal_subtype
expands_facilities

Use this data

Get every facility expansion signal for Meta and the companies you sell to, in the tools you already use.

  1. Ask Claude about it

    Connect Autobound to Claude, Claude Code or Cursor with MCP. Then ask: “What changed at Meta this week?”

  2. Send it to your own tools

    The Signal API returns facility expansion signals for any list of companies as JSON, for your CRM, warehouse or app.

  3. Try it free

    Sign up and spend your free credits on the companies you sell to.

    Start Free1,000 free credits

The API returns more than this page shows

This page shows a preview. The full news record in the Signal API and MCP can also have these 8 fields. Some fields are empty for some signals.

Company

  • linkedin_urlValue in the API
  • industriesValue in the API
  • employee_count_lowValue in the API
  • employee_count_highValue in the API
  • revenueValue in the API
  • descriptionValue in the API

Signal

  • signal_nameValue in the API
  • associationValue in the API
Show the full JSONThe record on this page and the API request

GET /v1/signals/957025d0-b026-d419-84d1-094358d5e6ad returns this record as JSON. POST /v1/companies/enrich returns every signal for meta.com.

{
  "signal_id": "957025d0-b026-d419-84d1-094358d5e6ad",
  "signal_type": "news",
  "signal_subtype": "expands_facilities",
  "detected_at": "2026-10-20T20:39:42+00:00",
  "company": {
    "name": "Meta",
    "domain": "meta.com"
  },
  "data": {
    "url": "https://www.theregister.com/systems/2026/10/20/tens-of-thousands-of-nvidia-gpus-sit-idle-in-metas-prometheus-supercluster-just-waiting-for-a-failure/5304269",
    "title": "Tens of thousands of Nvidia GPUs sit idle in Meta's Prometheus supercluster, just waiting for a failure",
    "author": "Tobias Mann",
    "excerpt": "systems And other fun facts about how Zuckercorp aims to keep a million GPUs running long enough to train a model More than 11 percent of the GPUs at Meta’s Prometheus supercluster in New Albany, Ohio, are either dead or sitting idle waiting to step in when the next drops out, Zuckercorp revealed this week. The massive pool of redundant GPUs is just one of several measures the hyperscaler has taken to keep its AI training runs on track. Prometheus is among Meta's largest compute deployments to date. Powered by Nvidia's Grace Blackwell and (soon) Vera Rubin rack systems, Meta says the supercluster will eventually scale to a gigawatt of capacity spanning about a million accelerators. But as anyone who has worked on a large scale compute cluster understands, whether for LLM training or traditional HPC workloads, more chips inevitably means more problems. In an eight-GPU node, the chance of having a GPU fail is relatively low. In a 100,000-GPU cluster, failures are unavoidable. Meta is building something that's 10x larger and requires distributed training runs across multiple datacenters. Keeping the entire thing humming long enough to reach the next checkpoint becomes a major headache. In a blog post published this week, Meta offered a unique look at the work it's done to keep failures from derailing the development of models like Muse Spark or its most recent release Muse...",
    "summary": "Meta is building and scaling its Prometheus supercluster compute deployment in New Albany, Ohio, to eventually reach a gigawatt of capacity spanning approximately one million accelerators.",
    "location": "New Albany, Ohio, United States",
    "planning": true,
    "image_url": "https://image.theregister.com/5304288.jpg?imageId=5304288&x=0&y=0&cropw=100&croph=100&panox=0&panoy=0&panow=100&panoh=100&width=1200&height=683",
    "confidence": 0.92,
    "published_at": "2026-10-20T20:39:42Z",
    "location_data": [
      {
        "city": "New Albany",
        "state": "Ohio",
        "region": "Northern America",
        "country": "United States",
        "continent": "Americas",
        "fuzzy_match": false
      }
    ],
    "article_sentence": "Meta is building something that's 10x larger and requires distributed training runs across multiple datacenters."
  }
}

Long text fields are shortened on this page.

Looking up one signal by its id is free. Enrich costs 2 credits per signal returned; a call with no results is free.